st558-project2
Predicting Popularity of Articles in the bus Channel
Claudia Donahue and Dane Korver 2022-06-28
Introduction
For this project, the dataset we are using summarizes a heterogeneous set of statistics about articles published by Mashable over a period of two years. The goal is to predict an article’s number of shares to social networks (its popularity). We wanted to look at the patterns in the articles that were shared. For example, is the timing of the article, the headline, and the article’s content all relevant in determining the number of times the article gets shared? What about whether an article had a polarizing title versus a generic non-polarizing title. Then, we wanted to find out whether the number of keywords associated with an article impacted the number of shares it received. Here are our findings for studying how to predict the number of shares in social networks (popularity).
Data
We’ll begin by reading in the data set and looking at how it’s structured.
data <- readr::read_csv(file = "OnlineNewsPopularity.csv",
                        show_col_types = FALSE
                        )
# Look at structure of data set
str(data)
## spec_tbl_df [39,644 × 61] (S3: spec_tbl_df/tbl_df/tbl/data.frame)
##  $ url                          : chr [1:39644] "http://mashable.com/2013/01/07/amazon-instant-video-browser/" "http://mashable.com/2013/01/07/ap-samsung-sponsored-tweets/" "http://mashable.com/2013/01/07/apple-40-billion-app-downloads/" "http://mashable.com/2013/01/07/astronaut-notre-dame-bcs/" ...
##  $ timedelta                    : num [1:39644] 731 731 731 731 731 731 731 731 731 731 ...
##  $ n_tokens_title               : num [1:39644] 12 9 9 9 13 10 8 12 11 10 ...
##  $ n_tokens_content             : num [1:39644] 219 255 211 531 1072 ...
##  $ n_unique_tokens              : num [1:39644] 0.664 0.605 0.575 0.504 0.416 ...
##  $ n_non_stop_words             : num [1:39644] 1 1 1 1 1 ...
##  $ n_non_stop_unique_tokens     : num [1:39644] 0.815 0.792 0.664 0.666 0.541 ...
##  $ num_hrefs                    : num [1:39644] 4 3 3 9 19 2 21 20 2 4 ...
##  $ num_self_hrefs               : num [1:39644] 2 1 1 0 19 2 20 20 0 1 ...
##  $ num_imgs                     : num [1:39644] 1 1 1 1 20 0 20 20 0 1 ...
##  $ num_videos                   : num [1:39644] 0 0 0 0 0 0 0 0 0 1 ...
##  $ average_token_length         : num [1:39644] 4.68 4.91 4.39 4.4 4.68 ...
##  $ num_keywords                 : num [1:39644] 5 4 6 7 7 9 10 9 7 5 ...
##  $ data_channel_is_lifestyle    : num [1:39644] 0 0 0 0 0 0 1 0 0 0 ...
##  $ data_channel_is_entertainment: num [1:39644] 1 0 0 1 0 0 0 0 0 0 ...
##  $ data_channel_is_bus          : num [1:39644] 0 1 1 0 0 0 0 0 0 0 ...
##  $ data_channel_is_socmed       : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ data_channel_is_tech         : num [1:39644] 0 0 0 0 1 1 0 1 1 0 ...
##  $ data_channel_is_world        : num [1:39644] 0 0 0 0 0 0 0 0 0 1 ...
##  $ kw_min_min                   : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ kw_max_min                   : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ kw_avg_min                   : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ kw_min_max                   : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ kw_max_max                   : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ kw_avg_max                   : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ kw_min_avg                   : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ kw_max_avg                   : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ kw_avg_avg                   : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ self_reference_min_shares    : num [1:39644] 496 0 918 0 545 8500 545 545 0 0 ...
##  $ self_reference_max_shares    : num [1:39644] 496 0 918 0 16000 8500 16000 16000 0 0 ...
##  $ self_reference_avg_sharess   : num [1:39644] 496 0 918 0 3151 ...
##  $ weekday_is_monday            : num [1:39644] 1 1 1 1 1 1 1 1 1 1 ...
##  $ weekday_is_tuesday           : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ weekday_is_wednesday         : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ weekday_is_thursday          : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ weekday_is_friday            : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ weekday_is_saturday          : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ weekday_is_sunday            : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ is_weekend                   : num [1:39644] 0 0 0 0 0 0 0 0 0 0 ...
##  $ LDA_00                       : num [1:39644] 0.5003 0.7998 0.2178 0.0286 0.0286 ...
##  $ LDA_01                       : num [1:39644] 0.3783 0.05 0.0333 0.4193 0.0288 ...
##  $ LDA_02                       : num [1:39644] 0.04 0.0501 0.0334 0.4947 0.0286 ...
##  $ LDA_03                       : num [1:39644] 0.0413 0.0501 0.0333 0.0289 0.0286 ...
##  $ LDA_04                       : num [1:39644] 0.0401 0.05 0.6822 0.0286 0.8854 ...
##  $ global_subjectivity          : num [1:39644] 0.522 0.341 0.702 0.43 0.514 ...
##  $ global_sentiment_polarity    : num [1:39644] 0.0926 0.1489 0.3233 0.1007 0.281 ...
##  $ global_rate_positive_words   : num [1:39644] 0.0457 0.0431 0.0569 0.0414 0.0746 ...
##  $ global_rate_negative_words   : num [1:39644] 0.0137 0.01569 0.00948 0.02072 0.01213 ...
##  $ rate_positive_words          : num [1:39644] 0.769 0.733 0.857 0.667 0.86 ...
##  $ rate_negative_words          : num [1:39644] 0.231 0.267 0.143 0.333 0.14 ...
##  $ avg_positive_polarity        : num [1:39644] 0.379 0.287 0.496 0.386 0.411 ...
##  $ min_positive_polarity        : num [1:39644] 0.1 0.0333 0.1 0.1364 0.0333 ...
##  $ max_positive_polarity        : num [1:39644] 0.7 0.7 1 0.8 1 0.6 1 1 0.8 0.5 ...
##  $ avg_negative_polarity        : num [1:39644] -0.35 -0.119 -0.467 -0.37 -0.22 ...
##  $ min_negative_polarity        : num [1:39644] -0.6 -0.125 -0.8 -0.6 -0.5 -0.4 -0.5 -0.5 -0.125 -0.5 ...
##  $ max_negative_polarity        : num [1:39644] -0.2 -0.1 -0.133 -0.167 -0.05 ...
##  $ title_subjectivity           : num [1:39644] 0.5 0 0 0 0.455 ...
##  $ title_sentiment_polarity     : num [1:39644] -0.188 0 0 0 0.136 ...
##  $ abs_title_subjectivity       : num [1:39644] 0 0.5 0.5 0.5 0.0455 ...
##  $ abs_title_sentiment_polarity : num [1:39644] 0.188 0 0 0 0.136 ...
##  $ shares                       : num [1:39644] 593 711 1500 1200 505 855 556 891 3600 710 ...
##  - attr(*, "spec")=
##   .. cols(
##   ..   url = col_character(),
##   ..   timedelta = col_double(),
##   ..   n_tokens_title = col_double(),
##   ..   n_tokens_content = col_double(),
##   ..   n_unique_tokens = col_double(),
##   ..   n_non_stop_words = col_double(),
##   ..   n_non_stop_unique_tokens = col_double(),
##   ..   num_hrefs = col_double(),
##   ..   num_self_hrefs = col_double(),
##   ..   num_imgs = col_double(),
##   ..   num_videos = col_double(),
##   ..   average_token_length = col_double(),
##   ..   num_keywords = col_double(),
##   ..   data_channel_is_lifestyle = col_double(),
##   ..   data_channel_is_entertainment = col_double(),
##   ..   data_channel_is_bus = col_double(),
##   ..   data_channel_is_socmed = col_double(),
##   ..   data_channel_is_tech = col_double(),
##   ..   data_channel_is_world = col_double(),
##   ..   kw_min_min = col_double(),
##   ..   kw_max_min = col_double(),
##   ..   kw_avg_min = col_double(),
##   ..   kw_min_max = col_double(),
##   ..   kw_max_max = col_double(),
##   ..   kw_avg_max = col_double(),
##   ..   kw_min_avg = col_double(),
##   ..   kw_max_avg = col_double(),
##   ..   kw_avg_avg = col_double(),
##   ..   self_reference_min_shares = col_double(),
##   ..   self_reference_max_shares = col_double(),
##   ..   self_reference_avg_sharess = col_double(),
##   ..   weekday_is_monday = col_double(),
##   ..   weekday_is_tuesday = col_double(),
##   ..   weekday_is_wednesday = col_double(),
##   ..   weekday_is_thursday = col_double(),
##   ..   weekday_is_friday = col_double(),
##   ..   weekday_is_saturday = col_double(),
##   ..   weekday_is_sunday = col_double(),
##   ..   is_weekend = col_double(),
##   ..   LDA_00 = col_double(),
##   ..   LDA_01 = col_double(),
##   ..   LDA_02 = col_double(),
##   ..   LDA_03 = col_double(),
##   ..   LDA_04 = col_double(),
##   ..   global_subjectivity = col_double(),
##   ..   global_sentiment_polarity = col_double(),
##   ..   global_rate_positive_words = col_double(),
##   ..   global_rate_negative_words = col_double(),
##   ..   rate_positive_words = col_double(),
##   ..   rate_negative_words = col_double(),
##   ..   avg_positive_polarity = col_double(),
##   ..   min_positive_polarity = col_double(),
##   ..   max_positive_polarity = col_double(),
##   ..   avg_negative_polarity = col_double(),
##   ..   min_negative_polarity = col_double(),
##   ..   max_negative_polarity = col_double(),
##   ..   title_subjectivity = col_double(),
##   ..   title_sentiment_polarity = col_double(),
##   ..   abs_title_subjectivity = col_double(),
##   ..   abs_title_sentiment_polarity = col_double(),
##   ..   shares = col_double()
##   .. )
##  - attr(*, "problems")=<externalptr>
# Checking to see whether the data has missing values
sum(is.na(data))
## [1] 0
The data has just one column that is not numeric, and that column is the
first one and contains URLs for the Mashable articles for each
observation. We will keep it, but won’t use it in our models. The second
column, timedelta, is not useful for prediction either. We will drop
this one. The other columns contain numeric data that we may be able to
use to predict the number of shares. The last column is our target
variable, shares. The data is set up nicely for what we want to do.
# Dropping the timedelta column

library(plyr)
library(tidyverse)
data <- select(data, -timedelta)

# Add a day column for data exploration/plotting purposes
data$day <- case_when(
  data$weekday_is_monday == 1 ~ "Monday",
  data$weekday_is_tuesday == 1 ~ "Tuesday",
  data$weekday_is_wednesday == 1 ~ "Wednesday",
  data$weekday_is_thursday == 1 ~ "Thursday",
  data$weekday_is_friday == 1 ~ "Friday",
  data$weekday_is_saturday == 1 ~ "Saturday",
  data$weekday_is_sunday == 1 ~ "Sunday"
)
data$day <- as_factor(data$day)

#Converting categorical values from numeric to factor - Weekdays
data$weekday_is_monday <- factor(data$weekday_is_monday)
data$weekday_is_tuesday <- factor(data$weekday_is_tuesday)
data$weekday_is_wednesday <- factor(data$weekday_is_wednesday)
data$weekday_is_thursday <- factor(data$weekday_is_thursday)
data$weekday_is_friday <- factor(data$weekday_is_friday)
data$weekday_is_saturday <- factor(data$weekday_is_saturday)
data$weekday_is_sunday <- factor(data$weekday_is_sunday)

# Add a channel column
data$chan <- case_when(
  data$data_channel_is_lifestyle == 1 ~ "Lifestyle",
  data$data_channel_is_entertainment == 1 ~ "Entertainment",
  data$data_channel_is_bus == 1 ~ "Business",
  data$data_channel_is_socmed == 1 ~ "Social Media",
  data$data_channel_is_tech == 1 ~ "Technology",
  data$data_channel_is_world == 1 ~ "World"
)
data$chan <- as_factor(data$chan)

#Converting categorical values from numeric to factor - News subjects
data$data_channel_is_lifestyle <- factor(data$data_channel_is_lifestyle)
data$data_channel_is_entertainment <- factor(data$data_channel_is_entertainment)
data$data_channel_is_bus <- factor(data$data_channel_is_bus)
data$data_channel_is_socmed <- factor(data$data_channel_is_socmed)
data$data_channel_is_tech <- factor(data$data_channel_is_tech)
data$data_channel_is_world <- factor(data$data_channel_is_world)
Next we will begin our look at one specific channel (bus) by subsetting the data.
channel <- channel # set = to channel when ready to automate

channelNow <- paste("data_channel_is_", channel, sep = "")

cData <- data[data[channelNow] == 1, ] # Extract rows of interest
We then split the bus channel’s data into training and testing sets (70%
and 30%, respectively). We will only explore the training set, and will
keep the testing set in reserve to determine the quality of our
predictions. We will use the function createDataPartition() from the
caret package to split the data.
library(caret) # Using createDataPartition from caret

set.seed(33) # for reproducibility

# Index to split on
idx <- createDataPartition(y = cData$shares, p = 0.7, list = FALSE)

# Subset
training <- cData[idx, ]
testing <- cData[-idx, ]
Summarizations
Then we thought about the characteristics of an online article that might be associated with someone deciding to “share” the article to someone else.
We thought it was probably important to consider both the timing of the article, the headline, and the article’s content. By timing, we mean that perhaps some readers are more likely to click on an article and share it on the weekend because they generally have more free time to read. But then we plotted the number of articles published each day, and realized not much gets published on the weekend, compared to weekdays. To visualize this pattern, we created the chart below:
ggplot(data) +
  geom_bar(aes(x = day, fill = chan)) +
  labs(title = "Number of Articles by Day of Week",
       x = "Day of the Week",
       y = "Number of Articles",
       fill = "Channel")
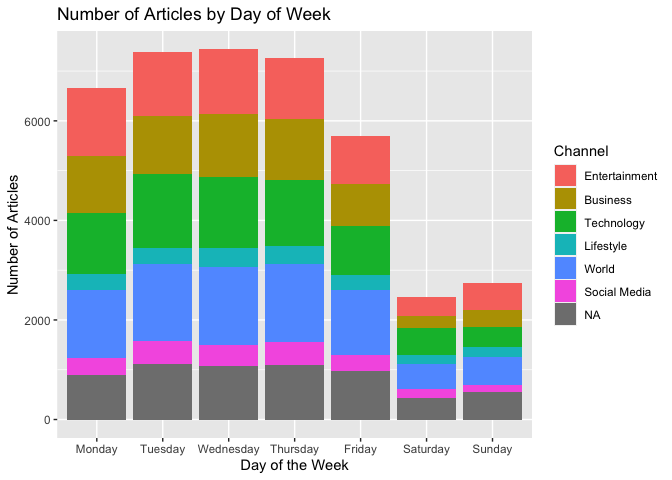 A table of
the above chart:
data %>% group_by(day,chan) %>%
  summarise(n=n(),
            Avg=mean(shares),
            Sd=sd(shares),
            Median=median(shares),
            Min=min(shares),
            Max=max(shares))
## `summarise()` has grouped output by 'day'. You can override using the
## `.groups` argument.

## # A tibble: 49 × 8
## # Groups:   day [7]
##    day     chan              n   Avg     Sd Median   Min    Max
##    <fct>   <fct>         <int> <dbl>  <dbl>  <dbl> <dbl>  <dbl>
##  1 Monday  Entertainment  1358 2931.  7176.   1100    59 112600
##  2 Monday  Business       1153 3887. 28313.   1400     1 690400
##  3 Monday  Technology     1235 2821.  3915.   1600   192  51000
##  4 Monday  Lifestyle       322 4346. 14073.   1600   109 196700
##  5 Monday  World          1356 2456.  6865.   1100    43 141400
##  6 Monday  Social Media    337 4010.  6046.   2300    53  57600
##  7 Monday  <NA>            900 6961. 17388.   1900     4 200100
##  8 Tuesday Entertainment  1285 2708.  6453.   1100    47  98000
##  9 Tuesday Business       1182 2932. 10827.   1300    44 310800
## 10 Tuesday Technology     1474 2883.  4722.   1600   104  88500
## # … with 39 more rows
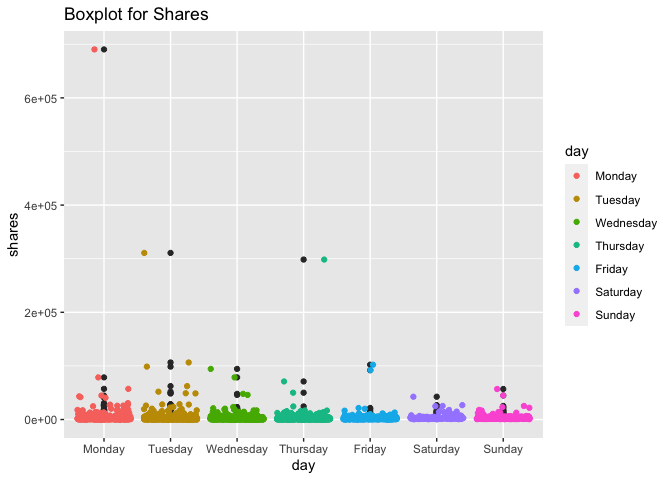
So we did away with that theory, and we will instead look at just the bus channel’s number of shares across days of the week.
ggplot(training, aes(x = day, y = shares)) +
  geom_boxplot() +
  geom_jitter(aes(color = day)) +
  ggtitle("Boxplot for Shares")
 A table of the above chart:
training %>% group_by(day,chan) %>%
  summarise(n=n(),
            Avg=mean(shares),
            Sd=sd(shares),
            Median=median(shares),
            Min=min(shares),
            Max=max(shares))
## `summarise()` has grouped output by 'day'. You can override using the
## `.groups` argument.

## # A tibble: 7 × 8
## # Groups:   day [7]
##   day       chan         n   Avg     Sd Median   Min    Max
##   <fct>     <fct>    <int> <dbl>  <dbl>  <dbl> <dbl>  <dbl>
## 1 Monday    Business   823 3659. 24585.   1400   112 690400
## 2 Tuesday   Business   818 3201. 12801.   1300    44 310800
## 3 Wednesday Business   886 2349.  5204.   1250    63  94400
## 4 Thursday  Business   857 2517. 10753.   1300    99 298400
## 5 Friday    Business   588 2432.  5934.   1400    22 102200
## 6 Saturday  Business   168 3933.  5075.   2500   150  42500
## 7 Sunday    Business   242 3738.  5560.   2200   692  56900
The boxplot shows the distribution of the number of shares by the day of the week. It can be a good way to see if we have any outliers with way more shares than a typical article in this channel.
We wanted to look at these outliers–the bus channel’s top articles by shares, so we grabbed a list of those URLs, along with the number of shares.
head(training[order(training$shares, decreasing = TRUE), c("url", "shares")], 10)
## # A tibble: 10 × 2
##    url                                                                   shares
##    <chr>                                                                  <dbl>
##  1 http://mashable.com/2013/04/15/dove-ad-beauty-sketches/               690400
##  2 http://mashable.com/2014/01/14/australia-heatwave-photos/             310800
##  3 http://mashable.com/2013/11/14/ibm-watson-brief/                      298400
##  4 http://mashable.com/2013/11/19/mapbox/                                106400
##  5 http://mashable.com/2013/10/18/edward-snowden-dont-have-nsa-document… 102200
##  6 http://mashable.com/2013/10/29/vampire-selfies/                        98700
##  7 http://mashable.com/2013/11/27/thanksgiving-times-square/              94400
##  8 http://mashable.com/2014/01/31/nsa-director-michael-rogers/            92100
##  9 http://mashable.com/2014/01/06/snapchat-hires-washington-lobbying-fi…  78600
## 10 http://mashable.com/2014/10/21/scientists-discover-the-origins-of-se…  78600
You can check out the article’s date and title within the URL and see what some of the most-shared articles were in the bus channel during the time period studied.
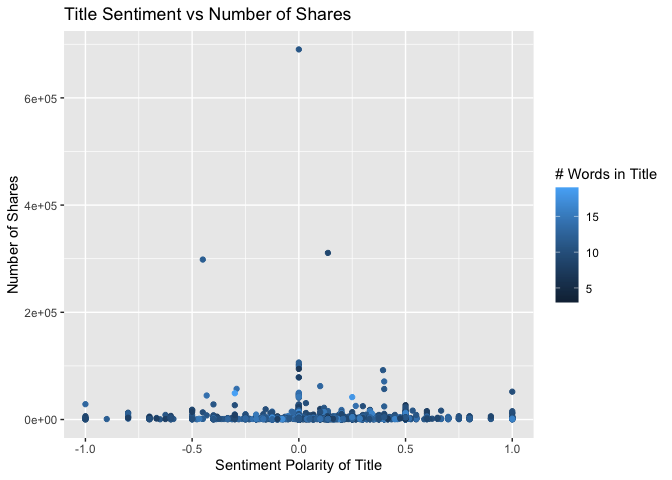
Then we wanted to create a visualization that would show us how the
variable title_sentiment_polarity seemed to impact the number of
shares. Our thought was that maybe an article with a more polarizing
title would get more shares than one less polarizing, as people want to
have some justification for urging a friend to spend time reading the
article. A polarizing sentiment could provide that justification for
some people. We will plot the polarity of the title’s sentiment and
include information on the number of words in the title.
ggplot(training, aes(x = title_sentiment_polarity,
                     y = shares,
                     color = n_tokens_title)) +
  geom_point() +
  labs(title = "Title Sentiment vs Number of Shares",
       x = "Sentiment Polarity of Title",
       y = "Number of Shares",
       color = "# Words in Title")
 A table of the above chart:
training %>% group_by(title_sentiment_polarity) %>%
  summarise(n=n(),
            Avg=mean(shares),
            Sd=sd(shares),
            Median=median(shares),
            Min=min(shares),
            Max=max(shares))
## # A tibble: 238 × 7
##    title_sentiment_polarity     n   Avg    Sd Median   Min   Max
##                       <dbl> <int> <dbl> <dbl>  <dbl> <dbl> <dbl>
##  1                   -1        13 4041. 7555.  1400     28 28600
##  2                   -0.9       1  891    NA    891    891   891
##  3                   -0.8       7 6743. 4251.  5000   1600 12700
##  4                   -0.7      10 1988. 1808.   945    747  5100
##  5                   -0.667     2 2350   778.  2350   1800  2900
##  6                   -0.65      1  448    NA    448    448   448
##  7                   -0.625     2 4734. 5467.  4734.   869  8600
##  8                   -0.6      17 2242. 1653.  1600    665  6700
##  9                   -0.588     1  950    NA    950    950   950
## 10                   -0.5      31 3339. 4704.  1400    380 18300
## # … with 228 more rows
In this plot of the impact of the title’s sentiment polarity on shares, an upward trend in the plotted points would indicate that articles with higher values of title sentiment polarity tend to be shared more often. Note that polarity values can be positive or negative.
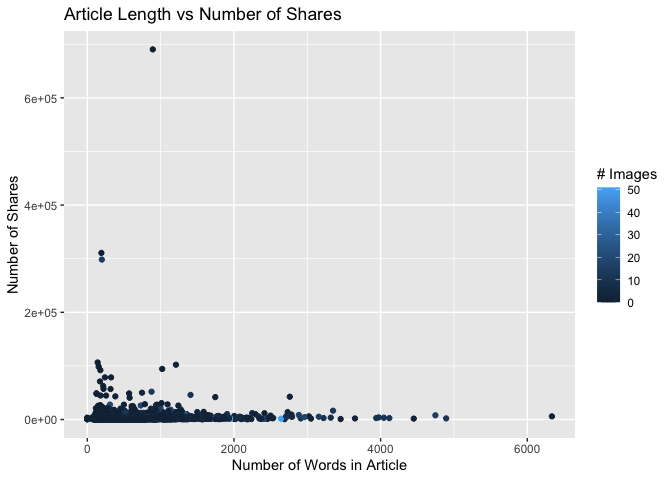
Finally, we thought about how the content of an article might lead someone to share it. Maybe people share shorter articles more than long ones. Maybe people like to share links with images more than links without images, we thought. So we took a look at an article’s length and number of images vs. number of shares.
ggplot(training, aes(x = n_tokens_content,
                     y = shares,
                     color = num_imgs)) +
  geom_point() +
  labs(title = "Article Length vs Number of Shares",
       x = "Number of Words in Article",
       y = "Number of Shares",
       color = "# Images")
 A table of the above chart:
training %>% group_by(n_tokens_content) %>%
  summarise(n=n(),
            Avg=mean(shares),
            Sd=sd(shares),
            Median=median(shares),
            Min=min(shares),
            Max=max(shares))
## # A tibble: 1,253 × 7
##    n_tokens_content     n   Avg    Sd Median   Min   Max
##               <dbl> <int> <dbl> <dbl>  <dbl> <dbl> <dbl>
##  1                0    13 1570.  862.   1300   590  3500
##  2               50     1 2200    NA    2200  2200  2200
##  3               61     1 3100    NA    3100  3100  3100
##  4               67     1  786    NA     786   786   786
##  5               72     1 1100    NA    1100  1100  1100
##  6               73     1 1000    NA    1000  1000  1000
##  7               76     2 4400   566.   4400  4000  4800
##  8               80     1  854    NA     854   854   854
##  9               81     1 1300    NA    1300  1300  1300
## 10               83     2 1779  1161.   1779   958  2600
## # … with 1,243 more rows
In this plot, a downward trend in plotted points would indicate that shorter articles generally get more shares, while an upward trend would indicate that longer articles achieve more shares.
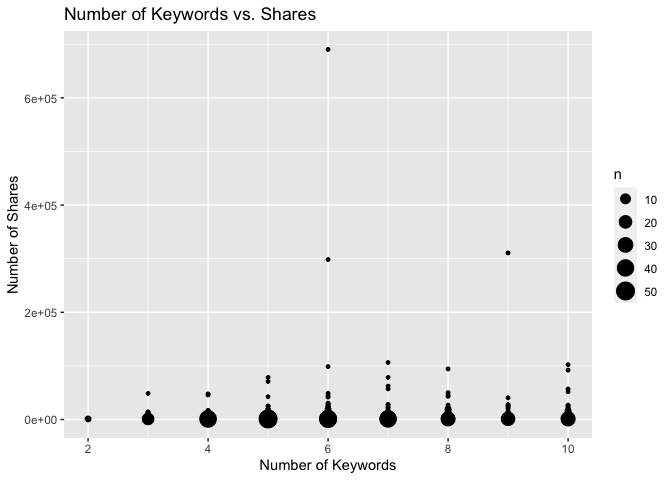
Next we looked at an article’s keyword characteristics. Within its metadata, a website can be assigned a number of keywords, which used to give search engines more information about the content. We wondered how the number of keywords related to the number of shares, given that this data is several years old, and that used to be considered a part of search engine optimization.
ggplot(training, aes(x = num_keywords,
                     y = shares)) +
  geom_count() +
  labs(title = "Number of Keywords vs. Shares",
       x = "Number of Keywords",
       y = "Number of Shares")
 A table of the above chart:
training %>% group_by(num_keywords) %>%
  summarise(n=n(),
            Avg=mean(shares),
            Sd=sd(shares),
            Median=median(shares),
            Min=min(shares),
            Max=max(shares))
## # A tibble: 9 × 7
##   num_keywords     n   Avg     Sd Median   Min    Max
##          <dbl> <int> <dbl>  <dbl>  <dbl> <dbl>  <dbl>
## 1            2    11 1140.   511.   1100   200   2100
## 2            3   179 2188.  4053.   1200   425  48700
## 3            4   533 2133.  3535.   1200    28  47800
## 4            5   847 2330.  4567.   1300    22  78600
## 5            6   845 3747. 26275.   1400   314 690400
## 6            7   641 2790.  6635.   1500    63 106400
## 7            8   485 2985.  6182.   1600   263  94400
## 8            9   333 3552. 17366.   1400   245 310800
## 9           10   508 3471.  7585.   1700   224 102200
The plot depicts circles sized by the number of articles falling into that category of number of keywords and number of shares. So you can how many keywords are typically used, and also whether any specific number of keywords tends to achieve more shares.
Before the modeling step, we took one final look at a few more of the other variables we thought might be important in predicting number of shares, based on the summaries above and our own experiences.
library(GGally)
training %>%
  select(self_reference_avg_sharess, LDA_00, rate_negative_words, shares) %>%
  GGally::ggpairs()
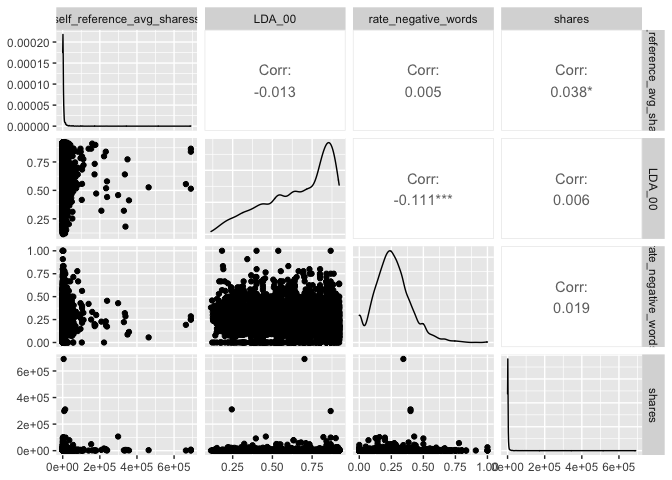
Looking across the bottom row of graphs, we can see whether any
relationships between shares and another variable are evident.
Modeling
Now we were ready to create some predictive models using the training data.
Linear Regression
Linear regression is a way of calculating the relationship between one
or more input/independent variables and an output/dependent variable.
(More than one input variable would make the model a multiple
regression) In this case, our output variables is shares, the number
of times a Mashable article was shared. A linear regression assumes that
one or more other variables are correlated with the number of shares,
and that the relationship can be visually represented as a straight
line. The mathematical equation for a basic linear regression is:
where y is the dependent variable, x is an independent variable, and A and B are coefficients for the line’s y-intercept and slope. The values for these coefficients are chosen to minimize the error between the model’s predictions and the actual outcomes in the training data.
With that, here we go! We are using the train() function from the
caret package to make the model. We will use the results of 5-fold
cross-validation to evaluate the performance of all our models and,
later, to compare them.
This first multiple regression (linear regression model extended to include more explanatory variables and/or higher order terms) will try to predict the number of shares based on most of the available data in our training dataset.
# building the model
fullFit <- train(shares ~ n_tokens_content + num_hrefs + num_self_hrefs +
                     average_token_length + num_keywords +
                     kw_min_max + kw_max_max + kw_avg_max + kw_max_avg +
                     kw_avg_avg + self_reference_min_shares + weekday_is_monday +
                     weekday_is_tuesday + weekday_is_wednesday +
                     weekday_is_thursday + weekday_is_friday +
                     global_subjectivity + title_sentiment_polarity,
              data = training,
              method = "lm", # linear regression
              preProcess = c("center", "scale", "nzv"),
              trControl = trainControl(method = "cv", number = 2)
              )
# look at the resulting coefficients
fullFit$finalModel
##
## Call:
## lm(formula = .outcome ~ ., data = dat)
##
## Coefficients:
##               (Intercept)           n_tokens_content
##                   2935.50                      42.60
##                 num_hrefs             num_self_hrefs
##                    233.19                     362.55
##      average_token_length               num_keywords
##                   -129.04                     594.04
##                kw_max_max                 kw_avg_max
##                   -475.84                     201.92
##                kw_max_avg                 kw_avg_avg
##                  -1875.72                    2653.14
## self_reference_min_shares         weekday_is_monday1
##                    312.14                     215.74
##       weekday_is_tuesday1      weekday_is_wednesday1
##                     24.31                    -293.27
##      weekday_is_thursday1         weekday_is_friday1
##                   -167.89                    -245.91
##       global_subjectivity   title_sentiment_polarity
##                    426.31                    -286.60
fullFit
## Linear Regression
##
## 4382 samples
##   18 predictor
##
## Pre-processing: centered (17), scaled (17), remove (1)
## Resampling: Cross-Validated (2 fold)
## Summary of sample sizes: 2191, 2191
## Resampling results:
##
##   RMSE      Rsquared     MAE
##   13120.87  0.003733027  2840.333
##
## Tuning parameter 'intercept' was held constant at a value of TRUE
The next multiple regresson model is a little more simplified and includes a smaller subset of variables that we think would be important.
smallFit <- train(shares ~ n_tokens_content + num_hrefs + num_self_hrefs +
                     average_token_length + num_keywords +
                     kw_min_max + kw_max_max + kw_avg_max + kw_max_avg +
                     kw_avg_avg + self_reference_min_shares +
                     global_subjectivity + title_sentiment_polarity,
              data = training,
              method = "lm",
              preProcess = c("center", "scale", "nzv"),
              trControl = trainControl(method = "cv", number = 2)
              )
# look at the resulting coefficients
smallFit$finalModel
##
## Call:
## lm(formula = .outcome ~ ., data = dat)
##
## Coefficients:
##               (Intercept)           n_tokens_content
##                   2935.50                      55.15
##                 num_hrefs             num_self_hrefs
##                    256.46                     350.88
##      average_token_length               num_keywords
##                   -127.22                     573.34
##                kw_max_max                 kw_avg_max
##                   -468.59                     184.51
##                kw_max_avg                 kw_avg_avg
##                  -1891.70                    2681.12
## self_reference_min_shares        global_subjectivity
##                    321.40                     429.76
##  title_sentiment_polarity
##                   -271.58
smallFit
## Linear Regression
##
## 4382 samples
##   13 predictor
##
## Pre-processing: centered (12), scaled (12), remove (1)
## Resampling: Cross-Validated (2 fold)
## Summary of sample sizes: 2190, 2192
## Resampling results:
##
##   RMSE      Rsquared    MAE
##   13081.04  0.01180274  2581.539
##
## Tuning parameter 'intercept' was held constant at a value of TRUE
Random Forest
Random forest is a tree-based method of prediction. It does not use all predictors available, but instead uses a random subset of predictors for each of many bootstrap samples / tree fits.
# load required package
library(randomForest)
# set up the mtry parameter
tunegrid <- expand.grid(.mtry=c(1:3)) # This is key for amount of time running

#train model
rfFit <- train(x = select(training, -url, -shares, -day, -chan),
                y = training$shares,
                method = "rf",
                tuneGrid = tunegrid,
                preProcess = c("center", "scale", "nzv"),
                trControl = trainControl(method = "cv",
                                         number = 2)
                )
rfFit
## Random Forest
##
## 4382 samples
##   58 predictor
##
## Pre-processing: centered (44), scaled (44), ignore (13), remove (1)
## Resampling: Cross-Validated (2 fold)
## Summary of sample sizes: 2191, 2191
## Resampling results across tuning parameters:
##
##   mtry  RMSE      Rsquared    MAE
##   1     12656.16  0.01825362  2464.486
##   2     12658.99  0.02420872  2502.443
##   3     12723.60  0.01731011  2549.061
##
## RMSE was used to select the optimal model using the smallest value.
## The final value used for the model was mtry = 1.
Boosted Tree
Boosted tree models is another tree-based method of prediction. Although, unlike random forest models, boosted tree models grow sequentially with each subsequent grown on a modified version of the original data and the predictions updated as trees grow.
# Load required packages
library(gbm)

# set up the parameters
gbmGrid <-  expand.grid(interaction.depth = c(1, 2, 3),
                        n.trees = c(25, 50),
                        shrinkage = 0.1,
                        n.minobsinnode = 10)

#train model
btFit <- train(x = select(training, -url, -shares, -day, -chan),
                y = training$shares,
                method = "gbm",
                tuneGrid = gbmGrid,
                preProcess = c("center", "scale", "nzv"),
                trControl = trainControl(method = "cv",
                                         number = 2)
                )
## Iter   TrainDeviance   ValidDeviance   StepSize   Improve
##      1 288087493.4952             nan     0.1000 -561418.0621
##      2 287860828.7437             nan     0.1000 56671.3984
##      3 285095265.4307             nan     0.1000 -1100097.8194
##      4 284467493.8354             nan     0.1000 235259.2129
##      5 284193293.1974             nan     0.1000 -40313.0410
##      6 280443985.6982             nan     0.1000 -511895.0322
##      7 278016576.1511             nan     0.1000 -1461288.7065
##      8 275329207.8459             nan     0.1000 -668617.7932
##      9 274759571.2117             nan     0.1000 -289182.6517
##     10 273112490.8919             nan     0.1000 -1779624.9541
##     20 268968003.7652             nan     0.1000 -2335485.1611
##     40 264761499.7104             nan     0.1000 -4142638.5512
##     50 264401696.5108             nan     0.1000 -988361.1718
##
## Iter   TrainDeviance   ValidDeviance   StepSize   Improve
##      1 291368925.1958             nan     0.1000 155312.9790
##      2 287040747.4688             nan     0.1000 -107070.5419
##      3 282799388.6724             nan     0.1000 -706847.5595
##      4 279507213.5972             nan     0.1000 -499615.4049
##      5 277100279.8098             nan     0.1000 -3057255.3242
##      6 274551581.3335             nan     0.1000 -562654.5876
##      7 274859950.4873             nan     0.1000 -1545746.7557
##      8 273775132.7227             nan     0.1000 -212431.6485
##      9 271167093.7276             nan     0.1000 -598061.1518
##     10 269826046.1752             nan     0.1000 -2820623.3452
##     20 260625087.1750             nan     0.1000 -1036708.5965
##     40 251430659.2297             nan     0.1000 -1176766.0006
##     50 245420553.4849             nan     0.1000 -1342836.8962
##
## Iter   TrainDeviance   ValidDeviance   StepSize   Improve
##      1 290931836.5567             nan     0.1000 56042.0406
##      2 286024651.0390             nan     0.1000 -552122.7793
##      3 283061733.7619             nan     0.1000 -1832115.0636
##      4 279319189.1518             nan     0.1000 -425829.9138
##      5 277006566.2737             nan     0.1000 -1389802.8945
##      6 273909064.6217             nan     0.1000 -1583132.2186
##      7 273592330.7563             nan     0.1000 -2466295.9116
##      8 271370350.0447             nan     0.1000 -1944447.5558
##      9 270888584.8068             nan     0.1000 -1786320.6129
##     10 268594311.5903             nan     0.1000 -1812178.6275
##     20 263196066.3378             nan     0.1000 -1977638.4136
##     40 247244007.0223             nan     0.1000 -2468086.5545
##     50 236154644.8754             nan     0.1000 -1647311.8173
##
## Iter   TrainDeviance   ValidDeviance   StepSize   Improve
##      1 67307039.5325             nan     0.1000 211396.0059
##      2 66114509.0493             nan     0.1000 220533.7607
##      3 65465741.7364             nan     0.1000 262556.5609
##      4 65275163.7105             nan     0.1000 240370.1658
##      5 65216910.1662             nan     0.1000  -37.5475
##      6 64474036.8086             nan     0.1000 72383.1349
##      7 64279657.1783             nan     0.1000 199953.8972
##      8 64197247.6418             nan     0.1000 90929.4655
##      9 63579054.3684             nan     0.1000 -235377.3599
##     10 63498759.8715             nan     0.1000 66497.8308
##     20 61730000.3276             nan     0.1000 -586520.0124
##     40 59951747.7531             nan     0.1000 -7760.4083
##     50 59112858.5861             nan     0.1000 -230279.8492
##
## Iter   TrainDeviance   ValidDeviance   StepSize   Improve
##      1 66374446.2227             nan     0.1000 544447.9642
##      2 65232016.1522             nan     0.1000 -67573.4101
##      3 64993234.3439             nan     0.1000 132328.0452
##      4 64337891.8154             nan     0.1000 34842.7591
##      5 63862635.5096             nan     0.1000 -317656.2692
##      6 63625766.7573             nan     0.1000 138439.7942
##      7 63517235.6089             nan     0.1000 -46250.5970
##      8 63280660.9322             nan     0.1000 -31045.1614
##      9 63179444.4251             nan     0.1000 44075.0783
##     10 62415109.5409             nan     0.1000 -38376.8912
##     20 59952896.1004             nan     0.1000 -279505.2256
##     40 55621946.2683             nan     0.1000 -283140.6824
##     50 53008066.9043             nan     0.1000 -235896.8802
##
## Iter   TrainDeviance   ValidDeviance   StepSize   Improve
##      1 67017188.4347             nan     0.1000 284300.5700
##      2 65737081.4035             nan     0.1000 569858.8243
##      3 65537834.9066             nan     0.1000 -40430.6729
##      4 65141869.9635             nan     0.1000 119232.7042
##      5 64946936.6954             nan     0.1000 61499.7670
##      6 64756816.9236             nan     0.1000 112381.9938
##      7 63633174.1839             nan     0.1000 -166019.9621
##      8 62730162.6970             nan     0.1000 234786.5690
##      9 62826991.4284             nan     0.1000 -337559.2295
##     10 62520612.5704             nan     0.1000 -32293.2126
##     20 59283735.5918             nan     0.1000 -254300.6714
##     40 55289600.4535             nan     0.1000 -76238.8660
##     50 53393522.4133             nan     0.1000 -300770.8015
##
## Iter   TrainDeviance   ValidDeviance   StepSize   Improve
##      1 176986371.0040             nan     0.1000 -280735.0969
##      2 176403005.5407             nan     0.1000 79539.4763
##      3 175724796.6880             nan     0.1000 327662.6485
##      4 173743487.0645             nan     0.1000 -305510.0523
##      5 172307644.1667             nan     0.1000 -622778.0314
##      6 171832971.3439             nan     0.1000 -949781.8493
##      7 171659835.5925             nan     0.1000 -744554.9790
##      8 170535163.4422             nan     0.1000 -1283604.5834
##      9 170080423.0582             nan     0.1000 -684263.7773
##     10 169390619.8039             nan     0.1000 -731684.7358
##     20 163306138.0289             nan     0.1000 -311194.2845
##     25 161286735.8306             nan     0.1000 -1330919.4557
Comparison
We compared all four of these models using the test dataset.
# full fit multiple regression model
fullPred <- predict(fullFit, newdata = testing)
# selected variable multiple regression model
smallPred <- predict(smallFit, newdata = testing)
# random forest
rfPred <- predict(rfFit, newdata = testing)
# boosted tree
btPred <- predict(btFit, newdata = testing)
Now we will compare the four candidate models and choose one “winner”:
# Create a named with results (Rsquared values) for each model
results <- c("Full Fit" = max(fullFit$results$Rsquared),
           "Small Fit" = max(smallFit$results$Rsquared),
           "Random Forest" = max(rfFit$results$Rsquared),
           "Boosted Tree" = max(btFit$results$Rsquared))

# RSquared Values are:
results
##      Full Fit     Small Fit Random Forest  Boosted Tree
##   0.003733027   0.011802738   0.024208725   0.002898986
# The best model based on the highest R-squared value is:
winner <- results[which.max(results)]
winner
## Random Forest
##    0.02420872
Above is our winning model for the bus channel based on it having the highest R-Squared value of 0.0242087! Our models are not doing that great, and only explain a small percentage of the variation in number of shares, but let’s not let that dampen our enthusiasm!
If we wanted to improve upon these models, we could increase the tuning
value of mtry in the Random Forest model. The cost would be the model
would take a lot longer to train. We also considered trying to predict
the
instead of
shares itself, but decided that was outside the scope of
the assignment.
Automation
We generated these reports automatically for each channel (“lifestyle”,
“entertainment”, “bus”, “socmed”, “tech”, and “world”) by creating a
function that uses the rmarkdown package to render a Github document
with a params option, and then using a for loop to execute that
function for each channel in a list. That’s how the bus channel page
you’re reading was generated!
The code we used to automate the rendering is visible at the main page for this project here.